Find the cheapest AI model that's good enough
- 10k free credits
- No card
Test your real prompt on up to 20 AI models side by side, find the cheapest that passes your rule, and monitor for changes.
For product teams, founders and agencies. No code, no SDK.
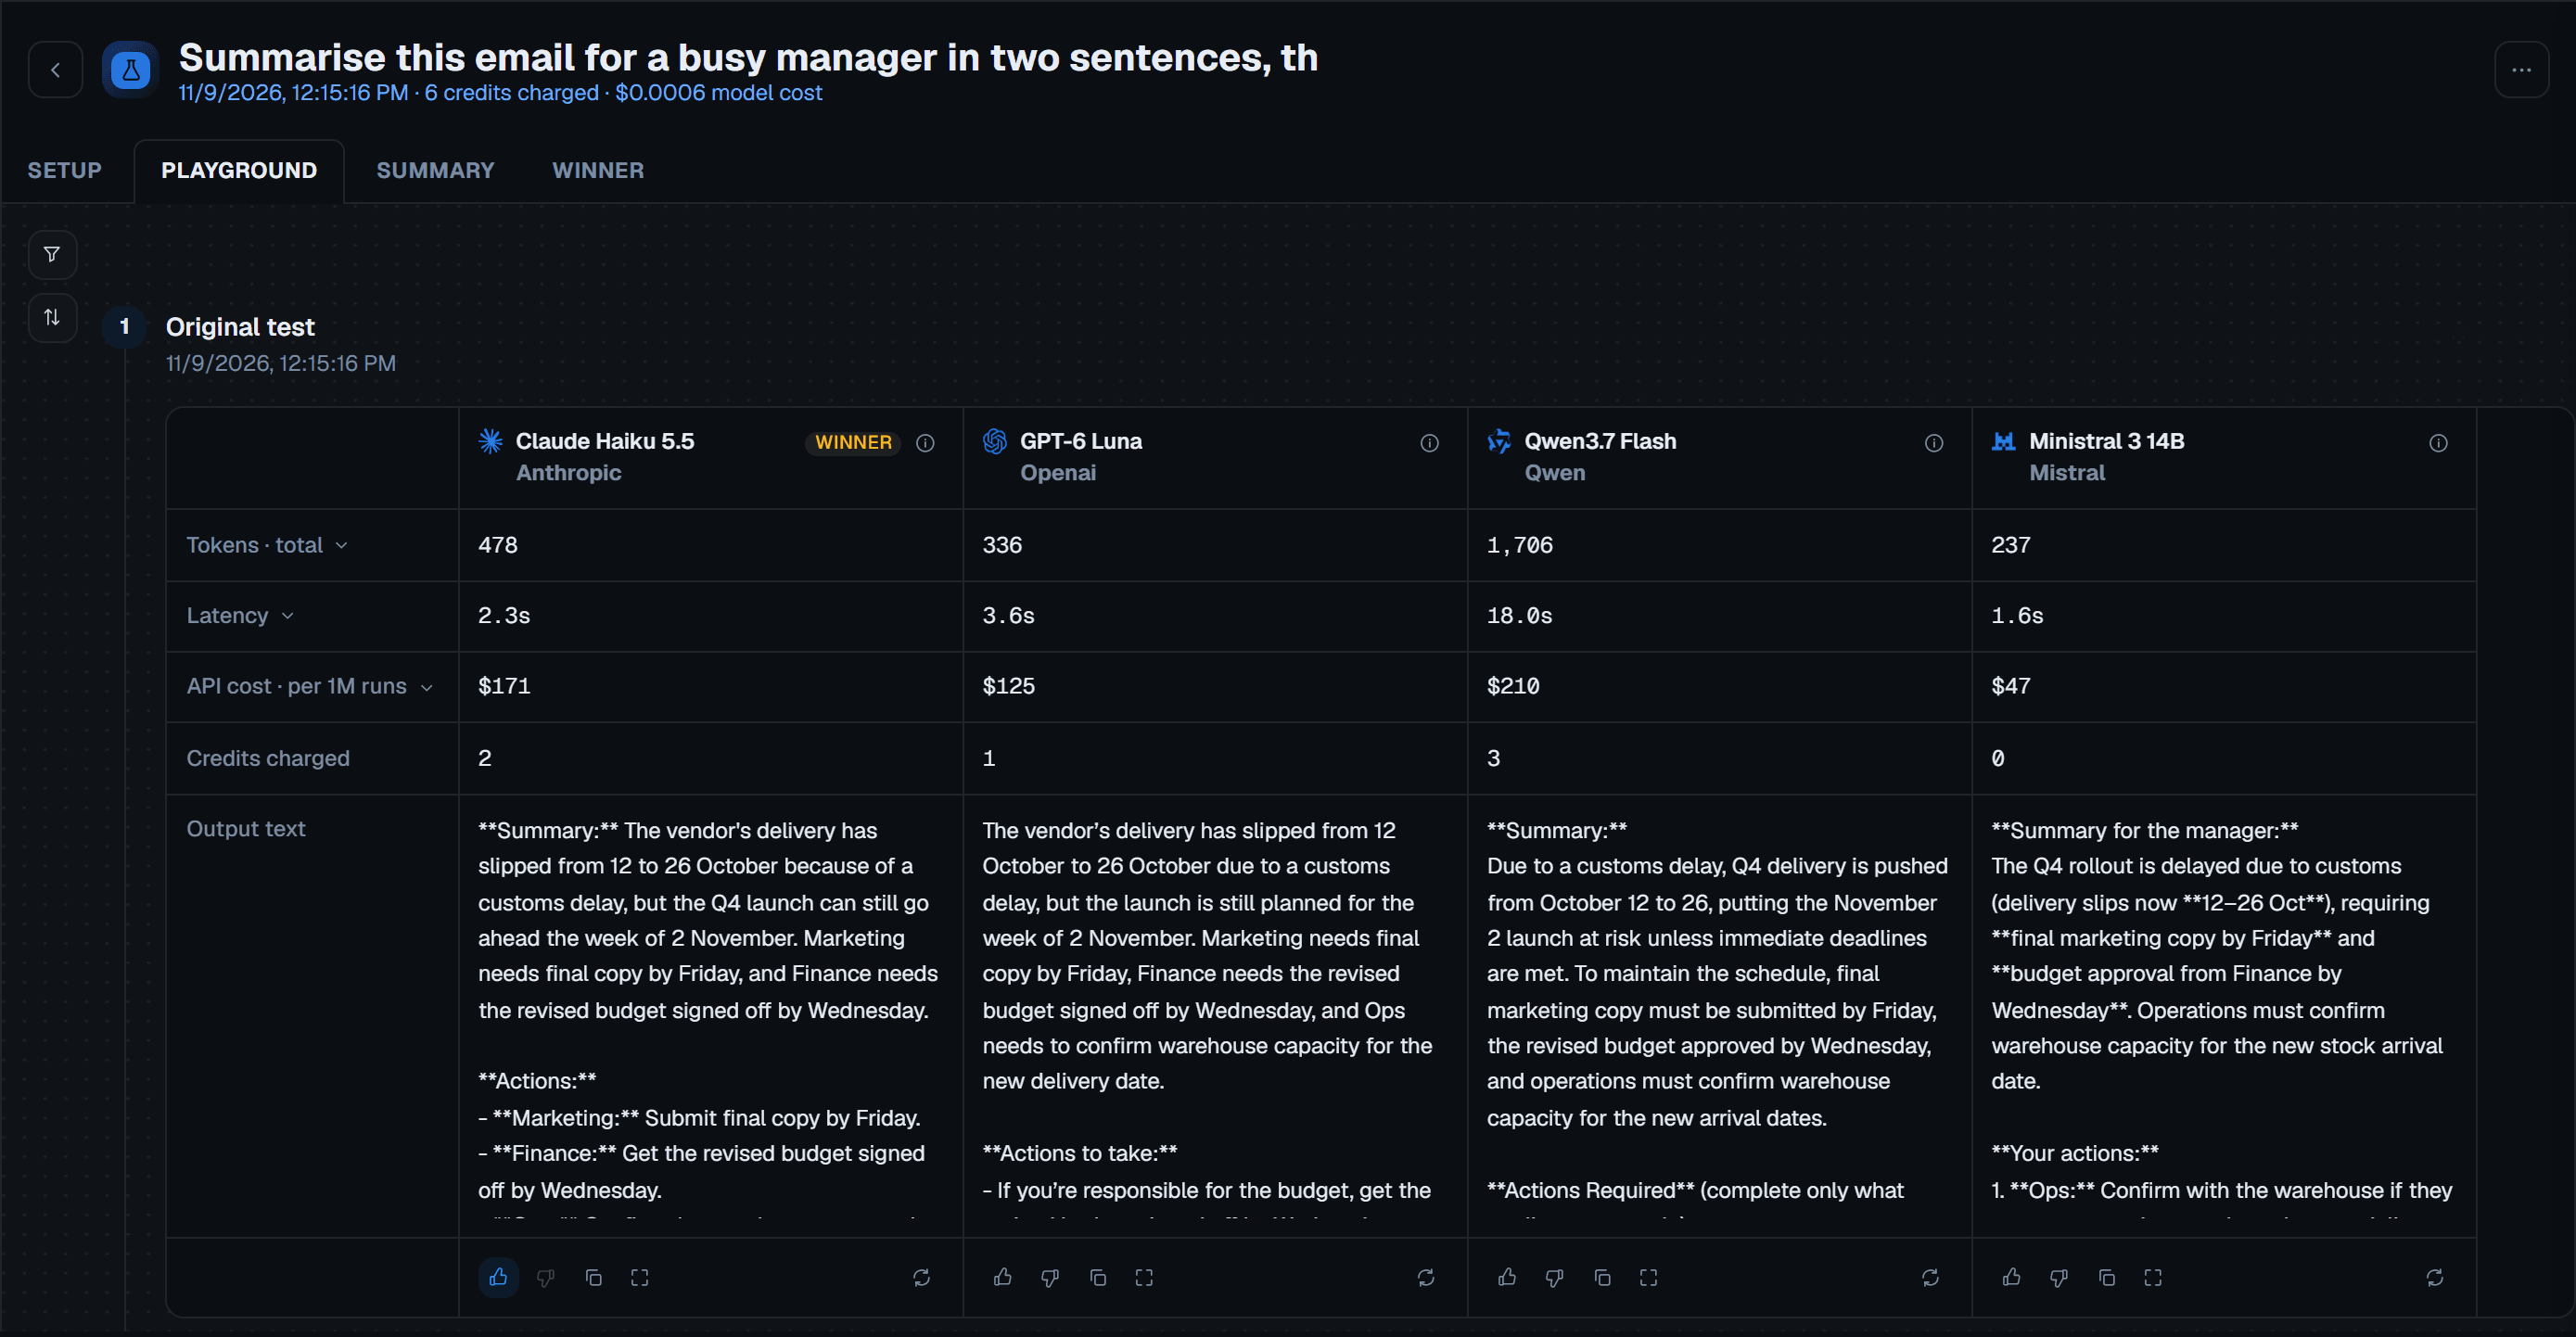


Leaderboards show who's smartest. Your prompt shows who's good enough.
Your prompt runs on every model you pick at once. Test AI models checks every answer and picks the one that does the job for less.
Extract the carrier, pickup date and rate from this rate confirmation as JSON.
 Anthropic
 OpenAI
 Google
 xAI
 DeepSeek
 Mistral
 Moonshot
 Qwen
 Perplexity
- Cost
- Speed
- Quality
- Reliability
- Savings
| Model | Cost per 1M runs | Speed | Your rule |
|---|---|---|---|
 Grok 4.3Winner | $84 | 2.1 s | Pass |
 GPT-5.5 | $1,080 | 18 s | Pass |
$996 saved per 1M runs
AI model testing without writing code
Test your real prompt on many models, check the answers against your own rule, monitor them for changes, and explore what wins.


Manage Home dashboard and analytics, projects, credits, billing and spend caps, help, docs and status, in the app.
Teams with real API volume
Not just a leaderboard: we test on your prompt. Not a dev tool: no code, no SDK. Not a big contract: pay as you go, or PRO at $20 a month.

Software agencies
Ship AI features for clients and back every model choice with side-by-side cost data instead of a hunch.

AI agent teams
Test every model-calling step of an agent as one workflow and see which steps can move to a cheaper model.

LLM product teams
Test the high-volume production steps with your real prompts and see the real latency and real cost of each run.
Proof you can open and judge for yourself
Tested on real freight documents
We tested 14 AI models on freight rate confirmations.
A test run for Zonik AI, a logistics product we co-founded. A small, real-world test, not a ranking of AI models and not a production saving. Costs are list prices on September 16, 2026.
Read the full test (opens in a new tab)
Benchmarks
Which model wins which kind of task, from the accounts that share their results. A public page.
See the public Benchmarks (opens in a new tab)Contra × Bubble award
Best Use of AI at the Bubble × Contra AI hackathon, December 2025, for the first version of the platform.
Read the story (opens in a new tab)
The docs
How every feature works, what it costs and where your prompt goes, for people who read before they sign up.
Read the docs (opens in a new tab)
Estimate your API overspend in a minute
Put in your monthly bill and two estimates. See what switching the right steps could save, then replace the estimates with a free test on your own prompt.
Your inputs
These start as example numbers, not our claim. The two percentages are your estimate. A free test on your real prompt replaces them with measured numbers.

Your prompts stay yours
Prompts go only to the models you pick. A task label goes once to Anthropic (or OpenAI as a fallback), and judge models see your prompt only if you run a quality check.
Hosted in Frankfurt, and each account only sees its own data.
HTTPS everywhere, hashed passwords, and provider keys kept server-side.
Kept until you delete it. Your prompts stay private unless you share a test yourself, and you can turn off sharing to Benchmarks in Settings.


Pay only for what you use
PRO adds up to 25 alerts, alerts on whole workflows and 20 models per test. Credits pay for every run and never expire, PRO's included.

Pay as you go
A prepaid credit wallet. Top up when you need more.
- Models per testUp to 10
- Smart alerts1, on a test
- Credits10,000 free on signup
- $10 top-up buysabout 33,000 credits
- Credits expireNever

PRO
The same wallet, plus 50,000 credits every month and cheaper top-ups.
- Models per testUp to 20
- Smart alerts25, on tests and workflows
- Credits50,000 every month
- $10 top-up buysabout 66,000 credits
- Credits expireNever, the monthly ones included
Common questions about model testing
Anything else, write to us or book a demo.
Which AI model should I use for my task?
It depends on the task, so test it on your own prompt. Run the models you are considering side by side and compare the answers, cost and speed. Add a quality check with a rule a good answer must meet, and the test shows the cheapest model that passed. For a starting point, Benchmarks shows which model people pick most for each kind of task.
How do I test several AI models at once?
Start a compare test: paste your prompt, pick up to 10 models (20 on PRO) and run them. Every answer comes back side by side with its tokens, speed and cost.
What is the cheapest AI model that is good enough?
There is no single answer, because good enough depends on your task. Write a pass rule in plain words and run the quality check: the test's Summary then shows the cheapest model whose answer passed, among the models you tested. Try cheaper models runs your prompt on cheaper models and checks them the same way.
How is this different from a benchmark?
A benchmark scores models on someone else's prompts. Here the models answer your own prompt with real API calls and are checked against your own rule, so you see what each answer costs and which ones pass for your task.
Are these real API calls or cached results?
Real API calls, always. We send your prompt live to each model's API in parallel. Results are never cached or pre-computed. This means the token counts and speeds come from real calls, and the cost is calculated from the tokens each model used at its current price. Speed varies from run to run.
What does the quality check do?
You write a pass rule in plain words, for example "Replies with only one word: billing, bug or question." Two cheap judge models read each answer and mark it pass or fail. If they disagree, a third decides. If there is still no majority, the answer is marked uncertain, never a pass. A judge never comes from the same company as the answer it judges. It is a check against your rule, not a guarantee, so look closely at the answers that matter.
How many models can I test at once?
Up to 10 on Pay as you go and up to 20 on PRO. The limit applies when the run starts.
What is a reliability check?
It repeats a finished test's exact prompt and settings 2, 5 or 10 times across the models you choose, so you can see how much the answers, speed and cost vary from run to run.
What do alerts watch?
An alert re-runs a test or a workflow daily, weekly or monthly and compares it with the winner you picked. Cost changes are reported straight away. A model getting slower, or its answer changing, has to show on two checks in a row. An alert tells you something is different, not that it is worse - the quality check does that. Pay as you go has 1 alert, on a test. PRO has up to 25, on tests and workflows.
How accurate are cost figures and estimates?
What a run cost is calculated from the tokens each model really used and its current price, so it is exact for that run. The estimate you see before a run is a worst case, shown in credits with no markup, assuming the longest possible answer from every model, so the real charge is usually lower. A savings projection compares your current monthly bill with each alternative model's measured cost per call. It is a cost comparison only, never a verdict on quality.
What do I get when I create an account?
A 10,000 credit signup gift: 3,000 credits for confirming your email, 4,000 for running your first test and 3,000 for a short survey. 10,000 credits equal $1 of real model usage, enough for several small tests. After that you top up from $10 or choose PRO. Credits never expire, the 50,000 PRO adds each month included.
How do workflows work?
A workflow is a set of up to 10 tests, each with its own prompt, models and settings, run together and compared together. Each step runs on its own prompt, so one step's answer is never fed into the next. Every run is kept on the workflow's Runs tab, where you can compare runs and see what changed since the previous one in cost, speed and answers. You can put a spend cap on a run, schedule it as a workflow alert on PRO, or import the model-calling steps from an n8n file.
Find the cheaper model before your next invoice
- 10k free credits
- No card
- No API keys